
Generative AI in ecommerce: what to build first and how


Contents
Generative AI in ecommerce creates text, images and conversations from your catalog and customer context, and the first project should be the one your data can already support. Product content grounded in a clean PIM usually clears that bar.
Shopping assistants and agent-ready feeds follow, once attribute and stock data are reliable. Forecasting and dynamic pricing are largely classical machine learning and belong in a different budget line. The right order depends on how complete your attributes are, how costly an error is per attribute type, and how much review capacity you have.
What is generative AI in ecommerce, and how does it differ from classical retail AI?
Generative AI in ecommerce uses large language models and image models to create product copy, visuals, and conversation, while classical retail AI scores, ranks, and forecasts. That split shapes the AWS vs Azure decision for retailers, since Bedrock and Azure OpenAI Service cover generation while SageMaker and Azure Machine Learning handle the recommendation and demand models.
The failure modes differ too. A recommender returns a weak ranking, but a generative model can return a fluent, wrong claim about a product.
The split follows the job. Forecasting, pricing, and return-risk scoring stay with classical machine learning. Product content, conversational commerce, and agentic commerce, where an AI agent shops and checks out for the buyer, are generative work.
Netguru builds ecommerce platforms, AI product discovery, and LLM-based assistants and content pipelines for online retailers. We recommend starting with content grounded in your PIM data, because a generator fills sparse attributes with plausible guesses. If those attributes are thin, fix the catalog first.
Where retailers need search and merchandising to sit on top of that clean catalog, our Bloomreach consulting team can help connect it to AI product discovery.
The two approaches side by side:
| Dimension | Classical retail AI | Generative AI |
|---|---|---|
| Output | A score, rank, or forecast | New text, images, or dialogue |
| Typical jobs | Demand forecasting, dynamic pricing, return-risk scoring, collaborative filtering | Product descriptions, shopping assistants, virtual try-on, agent-driven checkout |
| Main inputs | Transaction and behavioral data | PIM attributes, policies, and inventory feeds, usually supplied through retrieval |
| Typical failure | Wrong ranking or forecast, visible in offline metrics | Fluent but wrong product claim, found only by eval sets or review |
| Cost driver | Training and feature pipelines | Tokens per call and human review time |
Which generative AI use cases should you build first?
Build PIM-grounded product copy first, then a retrieval-augmented generation (RAG) support assistant, and defer any use case that needs attributes your product information management (PIM) system lacks.
The money case is established. McKinsey Global Institute estimates that generative AI productivity gains could add $400-$660 billion in value to retail industries. That figure doesn't tell you what to build on Monday.
We suggest scoring each candidate from 1 to 3 on three axes: impact on revenue or cost, feasibility at your latency and cost-per-call budget, and PIM data-readiness. Data-readiness acts as a gate. A use case that scores 1 on it waits, whatever its other scores.
Illustrative scores, our judgement for a mid-size catalog with a half-populated PIM, not a benchmark:
| Use case | Impact | Feasibility | Data-readiness | Verdict |
|---|---|---|---|---|
| Product copy and attribute enrichment | 2 | 3 | 2 | Build first |
| Support assistant on RAG over policies and order data | 3 | 2 | 2 | Build second |
| Conversational search and query rewriting | 2 | 2 | 2 | Pilot after the assistant |
| Image variants and lifestyle backgrounds | 2 | 2 | 3 | Pilot where assets exist |
| Virtual try-on | 2 | 1 | 1 | Defer |
| Agentic checkout through ACP or AP2 | 3 | 1 | 1 | Defer |
Copy comes first because the failure is containable. Generate from structured PIM attributes, constrain output to a schema, and route every draft through human-in-the-loop review before publish. A written brand voice spec covering tone, allowed topics, and non-negotiables belongs in the prompt from day one.
The support assistant scores higher on impact but lower on feasibility. It needs clean return and shipping policies, an order-status API, and a handoff path to agents, so it follows copy.
Defer three things:
- Virtual try-on: it needs per-category image pipelines and fit data most PIMs don't hold.
- Agentic checkout: OpenAI's Agentic Commerce Protocol and Google's Agent Payments Protocol are still early, and payment authorization raises liability questions.
- Auto-published copy: skip review only after an eval set shows hallucination in product copy at an error rate you accept.
This ranking shifts with context. An apparel retailer with rich fit and fabric attributes may promote try-on, and a catalog of a few hundred SKUs can write copy by hand more cheaply than it can build an eval set.
How generative AI creates product content
Generative AI creates product content by turning product information management (PIM) attributes into JSON-schema-constrained copy, then passing every output through validation gates before it reaches the storefront. The model drafts. The PIM stays the source of truth. If your catalog data isn't clean enough to feed a model yet, it pays to choose a PIM service before building anything on top of it.
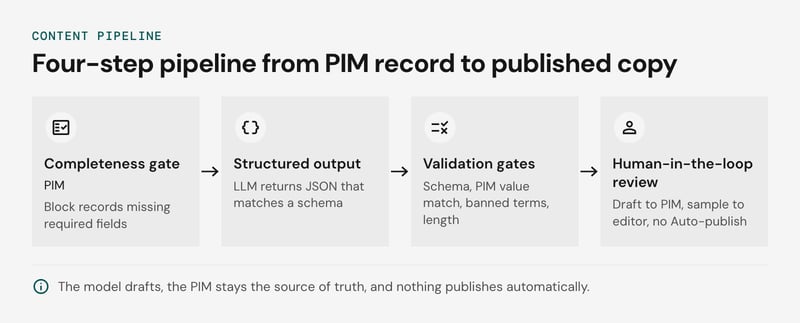
Natural language generation turns structured and unstructured data into written language, and in a catalog the structured data is the PIM record. The pipeline we recommend runs in four steps:
- Completeness gate. Export each SKU's attributes and block any record missing the required fields for its category. The threshold is yours to set, and it should differ for apparel and electronics.
- Structured output. Ask the large language model for JSON that matches a schema: title, short description, bullets, long description, and a claims_used array naming the PIM attribute behind each claim. Make optional attributes nullable.
- Validation gates. Reject output that fails schema validation. Compare every number, material, and dimension in the copy to the PIM value. Run a banned-term list and length limits.
- Human-in-the-loop review. Write passing copy back to the PIM as a draft and route a sample to an editor. Nothing publishes automatically.
Google's guidance on generative AI content says that producing many pages without adding value can violate its scaled content abuse policy. Attribute-grounded copy gives each page something specific to say.
Why sparse attributes produce invented facts
A SKU with three attributes leaves the model a long description to fill. It fills the gap with category priors: "breathable" for a running shirt, "water-resistant" for a jacket. That is hallucination in product copy, and it passes a fluency check because it sounds right.
The claims_used comparison catches it, since the invented claim has no source attribute. The cheaper fix is the completeness gate, plus an instruction to write a shorter description when data is thin.
Why brand voice drifts after the first SKUs
The first batch is usually reviewed by hand and the prompt gets tuned against it. Later batches run unattended across new categories, after prompt edits and model updates, and in our judgement the copy tends to settle into the model's default register. Brand voice guardrails need to be explicit and testable.
Practitioners call this a "Voice DNA": a formal document capturing brand personality, values, allowed topics, language priorities, and non-negotiables. Store it as a versioned prompt block with the banned-term list and three to five approved descriptions per category as few-shot examples. Pin the model version.
After that, treat every prompt or model change like a code change. Score a fixed evaluation set of SKUs, for example 50 (an illustrative size, not a benchmark), against the approved copy before rollout. Embedding distance to the approved-copy centroid gives a cheap drift signal, and an editor's read on a sample of each batch catches what the metric misses.
Generative AI product description generator: What the workflow needs
A generative AI product description generator needs large language models constrained by a JSON schema, a PIM-sourced attribute payload, and an eval set that scores every output before it publishes.
Start with prompting. Put the brand voice spec in the system prompt, add a handful of approved descriptions as few-shot examples, and force structured output: title, short description, bullets, meta description.
We recommend fine-tuning only when the eval set shows tone drift that examples can't fix, or when per-call cost at catalog volume justifies a smaller tuned model. It also ties you to a model version, so it is a later step.
Build the eval set before the first bulk run. Assume 300 SKUs, stratified by category and weighted toward hard cases: sparse attributes, variants, and regulated claims. Run four checks:
- Attribute faithfulness: a deterministic diff checks every dimension, material, and number in the copy against PIM fields. This is your hallucination gate.
- Schema and length: the output validates against the JSON schema, and meta descriptions stay near 155-160 characters, since search engines truncate at varying widths.
- SEO uniqueness: the primary keyword appears in the title and opening sentence, and no two SKUs share a meta description.
- Voice score: an LLM judge applies a rubric, calibrated against a human-reviewed sample.
Re-run the full set on every prompt or model change. Route failures and high-risk categories to human-in-the-loop review. Mass-produced thin pages risk Google's spam policies, so the uniqueness check carries real weight.
Can AI-generated visuals and virtual try-on pay off?
Virtual try-on pays off where returns come from fit, mainly apparel and footwear, and adds little where shoppers return items for taste or quality. Generated lifestyle imagery pays off differently: it lowers production cost per SKU, and it does not reduce returns on its own.
Loop found that size or fit drove 56% of apparel returns on its platform (Loop, 2026).
If size and fit drive your returns, try-on targets the cause. Where they don't, the returns problem sits in product data, photography accuracy, or merchandising. The trade-offs by category, as a judgement rather than a benchmark:
| Category | Main return driver | Try-on fit | Caveat |
|---|---|---|---|
| Apparel, footwear | Size, fit, drape | Strong | Garment fidelity on varied body types is the weak point |
| Beauty | Shade and undertone match | Moderate | Screen color calibration limits accuracy |
| Furniture, decor | Scale, placement, style | Low for generative | AR placement and 3D assets do this job; generation suits lifestyle scenes |
Test before scaling. Run try-on on one fit-sensitive category with a holdout group, and compare the return rate for that category against the holdout, not blended store-wide figures. Conversion lift claims from vendors are mostly self-reported, so treat them as hypotheses.
Brand-safety review for imagery and ad variants
Generated imagery and ad variants need human-in-the-loop review before publishing, because a model can alter a product's color, logo, stitching, or proportions without any error being raised. A reviewer comparing each output against the PIM record and the original product photo catches most of those defects.
A workable review gate checks:
- Product fidelity: color, texture, hardware, and logo match the source asset.
- Body and context: models, skin tones, and settings are not distorted or stereotyped.
- Claims: no ad variant implies a benefit, certification, or material the PIM doesn't support.
- Disclosure: synthetic imagery is labeled where required. Article 50 of the EU AI Act sets transparency duties for AI-generated image content, and counsel should confirm how it applies to catalog imagery.
Review every hero and ad image. For long-tail catalog images, we recommend sampling by risk tier: full review for new templates or categories, spot checks once the defect rate on an eval set stays low. Whether that sampling rate holds up is the next thing to measure.
How shopping assistants and support bots work
A shopping assistant or support bot works as retrieval-augmented generation over store data, so the LLM answers from retrieved catalog and policy records. Amazon Rufus and Walmart Sparky are the large-scale examples of this conversational commerce pattern, and the same architecture fits a mid-market storefront.
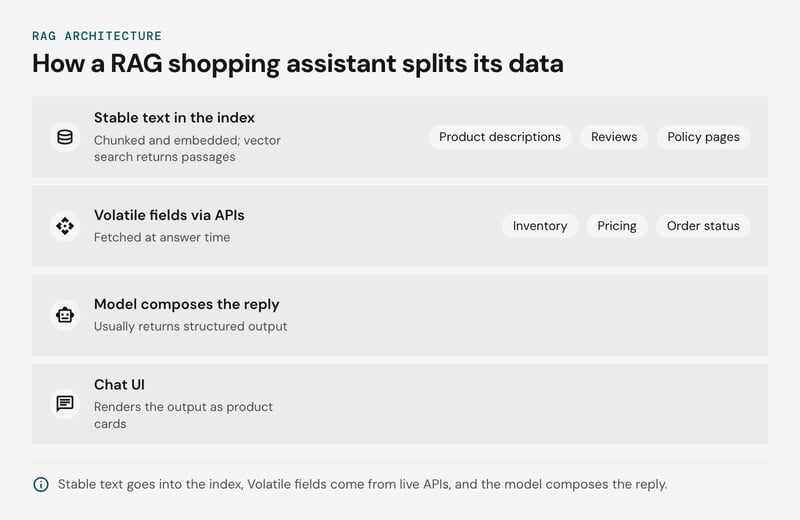
The bot reads two kinds of data, and the split drives most design decisions:
- Stable text goes into the index. Product descriptions, reviews and policy pages are chunked and embedded, and vector search returns candidate passages for each query.
- Volatile fields come from live APIs. Inventory, pricing and order status are fetched at answer time.
- The model composes the reply. It usually returns structured output that the chat UI renders as product cards.
A support bot also answers overnight, when no agent is watching, so its failure modes and handoff triggers need to be designed before launch.
Three failure modes to test first
Each row pairs a failure with an early warning sign you can watch in logs, the guardrail that prevents it, and the trigger that routes the chat to a person.
| Failure | Early sign | Guardrail | Handoff trigger |
|---|---|---|---|
| Stale stock: the index snapshot lags the warehouse, so the bot quotes availability from embedded text | Tickets about items that were "in stock" in chat but unavailable at checkout | Keep stock and price out of the index and fetch them by API at answer time | API timeout, or a mismatch between the quoted and live value |
| Return-policy edge cases: sale items, bundles, regional rules and exceptions sit on different pages and get retrieved piecemeal | Agents correcting the bot's return answers; replies that cite no policy clause | Chunk policy by condition, version it in one source, and make the reply quote the clause | Final-sale flag, a refund dispute, or any reply that would commit money |
| Retrieval misses: shopper wording differs from catalog attributes, or vector search returns the wrong variant | Rising reformulation rate; wrong size or color complaints; top scores drifting down after a catalog import | Hybrid search (keyword plus vector) with a minimum similarity score | Top score under the threshold, or two failed reformulations |
Retrieval misses are the hardest to catch because the model still writes a fluent answer from whatever it was given. A bot that declines to answer when retrieval is weak and passes the case to a person gives up some containment, but it avoids confident wrong answers at night.
A rule for when the bot may answer alone
We would let the bot reply without a human only when all three conditions hold:
- The top retrieval score clears the minimum threshold.
- Every live value quoted (stock, price, order status) matches the API response.
- The reply commits no money, such as a refund, a discount or a price match.
If any condition fails, the bot hands off. Set the threshold on your own catalog and ticket mix, because similarity scores vary with the embedding model and the content.
A handoff only helps if the agent receives the transcript, the retrieved passages and the order record. Otherwise the customer repeats everything, and the bot has added a step.
Build an eval set from real tickets, including stock questions and policy exceptions. Track wrong-answer rate and handoff rate against it on every index or prompt change.
What generative AI adds to site search
Generative AI adds meaning-based retrieval and query understanding to site search: embeddings and vector search match intent to products, and large language models rewrite messy queries before they reach the index.
We recommend adding these in a fixed order, driven by your search logs:
- Query rewriting first, when zero-result queries dominate. An LLM call turns "best running shoes under $100" into a category, a price filter, and synonyms, then runs against your existing index. Short queries repeat often, so responses cache well and latency stays low.
- Hybrid keyword and vector retrieval next. Embeddings catch the queries rewriting misses, but they only work as well as the product attributes in your PIM.
- Conversational search after the zero-result rate is low. A chat layer on a weak index produces fluent, wrong answers.
- Multimodal search last. It needs image embeddings across the whole catalog.
The AI product discovery guide covers the ranking and evaluation side in detail. Teams that want a managed route to this kind of AI-driven search can look at an Algolia implementation, which covers indexing, relevance tuning and integration with the existing commerce stack.

What generative AI adds to personalization and merchandising
Generative AI adds a language layer to personalization and merchandising. Large language models write the copy and rationale, while classic recommenders and pricing engines, which are not generative, still choose the products and prices. Each task has a different owner:
| Task | Selection layer (classical ML) | Generation layer (LLM) |
|---|---|---|
| Bundles | Co-purchase models, or embeddings and vector search for similar items | Writes the rationale from PIM attributes |
| Emails | Segment and send-time models pick products | Drafts subject line and body within a brand spec |
| Collections | Embeddings cluster the catalog by intent | Titles and describes; a human approves before publishing |
| Dynamic pricing | Pricing engine sets the price | At most phrases the offer; price fields are injected from the engine and kept out of the model's output |
Embeddings and vector search also cover cold-start items. A new SKU with no purchase history can still be placed beside similar products. A co-purchase model has no co-purchase data to work from in that situation.
Generation is only as good as the signals under it. A retailer with no clean event data and no working recommender gives an LLM nothing to verbalize. We recommend building the selection layer first: event tracking, a recommender, and clean PIM attributes. Add generation on top once those work.
Behavioral data is where the measured lift sits. Organizations using customer behavioral insights outperform peers by 85 percent in sales growth and more than 25 percent in gross margin (McKinsey - Capturing value from your customer data). That figure comes from customer analytics, not generative models. Read it as support for the groundwork, and test any lift from generated copy separately.
For emails at catalog scale, reuse the same brand voice spec in the system prompt. It also becomes the rubric for your eval set.
This layering is overkill for a small catalog with a handful of segments. There, templates with merge fields will usually ship faster and cost less per send than an LLM call per recipient.
Where classical ML still does the work: Forecasting, pricing and returns
Demand forecasting, dynamic pricing and returns triage still run on classical machine learning, with large language models limited to the text around those decisions.
We recommend a simple split. Numeric prediction goes to gradient-boosted trees or time-series models, and an LLM takes any step where the input or output is free text.
| Task | Input and output | Right tool | Reason |
|---|---|---|---|
| Demand forecasting | Sales history, promotions, seasonality in; SKU-level quantity out | Gradient-boosted trees, time-series models | Scored with error metrics such as WAPE; cheap per prediction at catalog scale |
| Dynamic pricing | Elasticity, competitor prices, stock in; bounded price out | Elasticity models, bandits, business rules | Prices need hard limits and an audit trail |
| Returns triage | Customer's written reason, photos, order data in; refund, exchange or inspection out | LLM extracts the reason into structured output; a classifier or rules pick the route | The input is text, the decision is a label |
| Customer messaging | Order status and return policy in; reply out | LLM with retrieval over the policy documents | Grounding limits hallucination about policy terms |
Returns triage is the hybrid case. Let the LLM turn "sleeve too tight, also the color looked different" into fields such as reason code and defect flag. A cheap classifier then routes the return, and refunds above a set value go to human-in-the-loop review.
This split has limits. A catalog of a few thousand SKUs may gain little from a trained forecaster over a seasonal-naive baseline. Before accepting any vendor claim of generative forecasting, run it against that baseline on a holdout period.

What is agentic commerce and what must merchants change?
Agentic commerce is shopping in which an AI agent searches, compares, and buys on the shopper's behalf, so merchants must expose complete, machine-readable product, stock, price, and checkout data.
A shopper asks ChatGPT for "best running shoes under $100" and gets products from several retailers. The agent can only rank a shoe if the feed states the attributes the query implies: price, size availability, cushioning, surface, and width. A listing that is a marketing paragraph with no typed fields is likely to be skipped or misdescribed.
That depends on AI-integrated commerce architecture that lets agents and storefronts work from the same structured product data.
What an agent-readable product record looks like
Here is a sketch for one variant of an invented shoe. The field names are illustrative and do not follow the schema of either protocol below, so map them to the current specification before building.
{
  "sku": "RS-204-BLK-10W",
  "gtin": "00123456789012",
  "title": "Stride Lite road running shoe",
  "category": "running-shoes/road",
  "attributes": {
    "surface": "road",
    "cushioning": "medium",
    "width": "wide",
    "size_us": 10
  },
  "price": { "amount": 89.00, "currency": "USD", "updated_at": "2026-01-15T09:30:00Z" },
  "availability": { "status": "in_stock", "quantity": 14, "updated_at": "2026-01-15T09:30:00Z" },
  "shipping": { "cost": 0.00, "currency": "USD", "min_days": 2, "max_days": 4 },
  "returns": { "window_days": 30, "free_returns": true }
}
Each group answers a question an agent has to resolve. The attributes match the shopper's query. Price and availability carry timestamps, so a stale value can be detected. Shipping and returns are numbers and booleans an agent can compare across merchants without parsing prose.
We have not surveyed which PIM or commerce platforms export these fields natively or support either protocol, and support is changing. Ask each vendor three questions:
- Can the PIM enforce required typed attributes per category?
- Can the platform publish price and stock with update timestamps?
- Which checkout protocols does the payment provider support today?
Merchant readiness checklist
Capturing any of that value through agents starts with data readiness. The list below is in order of work:
- Complete the attributes in your product information management (PIM) system. Audit required fields per category and export typed values (enums, units, GTINs) instead of free text. Where gaps exist, have an LLM propose values through structured output against a JSON schema that mirrors the PIM model, and put human review before anything is published.
- Fix stock and price feeds. Agents quote what the feed says, so a stale feed turns into a price or availability dispute at checkout. Set a freshness target per field and alert when it is breached.
- Choose checkout protocols. OpenAI's Agentic Commerce Protocol lets ChatGPT start a purchase while the merchant keeps order handling (Agentic Commerce Protocol GitHub repository, 2026). Google's Agent Payments Protocol uses signed mandates to prove the shopper authorized a purchase (Google Cloud Blog, 2025). Check which one your payment provider supports before building.
- Make policies machine-readable. Return windows, shipping cost and speed, and warranty terms belong in structured fields, because agents compare them alongside price.
- Test with real queries. Build an eval set of shopper-style questions (50 is an illustrative starting size, not a benchmark) and record whether an agent surfaces the right product with the right price.
The protocols are young and their specifications are still changing, so we recommend starting with steps 1 and 2. Clean attributes and fresh feeds also improve site search and marketplace listings, so the work pays off even if you adopt no protocol this year.
Merchants selling configured or quote-based products may find agent checkout out of scope for now, though complete attributes still help agents compare their products.
Risks of generative AI in ecommerce product content, and the controls
Hallucination in product copy is the main risk of generative AI in ecommerce content, and the control is human-in-the-loop review tiered by attribute risk. A model that invents a battery life costs more than one that writes a bland tagline.
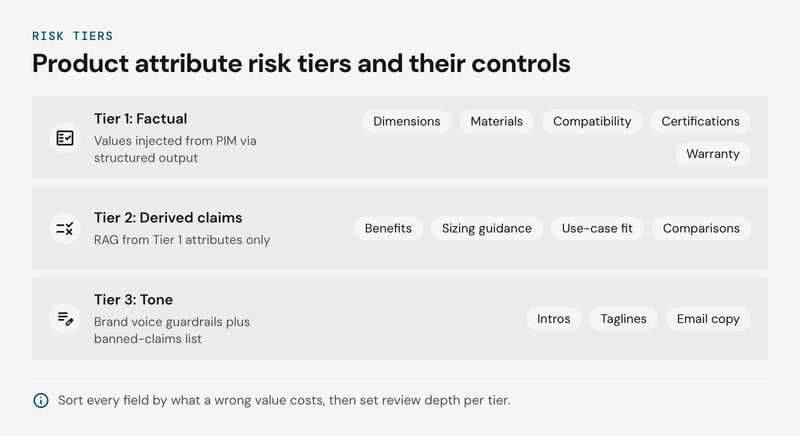
We recommend sorting every field by what a wrong value costs, then setting the review depth per tier. Dimensions, materials, compatibility, and certifications are never generated freely: values come from the PIM or supplier data, and the model only phrases them.
The tiers side by side:
| Tier | Attributes | Generation rule | Review |
|---|---|---|---|
| 1: Factual | Dimensions, materials, compatibility, certifications, allergens, warranty | Values injected from PIM via structured output; model cannot add or alter them | Schema and value checks on every record; human sign-off on any changed value |
| 2: Derived claims | Benefits, sizing guidance, use-case fit, comparisons | Retrieval-augmented generation from Tier 1 attributes only | Automated check that each claim traces to a source attribute; humans review the failures |
| 3: Tone | Intros, taglines, email copy | Brand voice guardrails in the prompt plus a banned-claims list | Sampled review; an illustrative starting rate is 5-10% of output, tuned to your defect rate |
Tier 1 needs no human reading when the pipeline is deterministic. Validate the output against the source record, and reject any number, unit, or certification string absent from it.
Disclosure and regulation
- Reviews: The FTC's final rule on fake reviews and testimonials covers AI-generated reviews from people who don't exist or never used the product. Never generate reviews, and keep synthetic text out of review feeds (Federal Trade Commission, 2024).
- EU transparency: Article 50 of the EU AI Act requires users to be told when they are talking to an AI system, which covers shopping assistants. Its text-labeling duty is tied to public-interest content, so product copy is a lower-risk case. Verify the current application dates with counsel.
- Search: Google Search Central accepts AI-generated content but treats mass-produced pages that add no value as spam. Tier 3 volume is where that applies.
Privacy and IP
Strip customer names, order IDs, and emails from support tickets and reviews before they reach a prompt or a fine-tuning set. For IP, confirm that supplier descriptions and images are licensed for model input, and screen output for competitor trademarks.
The NIST AI Risk Management Framework gives a vocabulary for logging these controls, and its generative AI profile (AI 600-1) calls hallucination "confabulation". Where Tier 1 data is thin, the fix is better PIM data. A stricter prompt does not supply attributes the record lacks.
Should you build, buy, or use platform features?
Use platform features such as Shopify Magic for a single-storefront catalog, buy PIM-native tooling for multichannel catalogs, and build only when large language models need your own product data rules and review workflow. Cost per SKU rarely decides it. Whichever route you take, plan early how you will connect your PIM to ecommerce channels so generated content draws on clean, governed product data.
The model below uses illustrative assumptions, not benchmarks. Substitute your own rates.
Worked example: cost per SKU. Assume 50,000 SKUs, a mid-tier LLM at $3 per million input tokens and $15 per million output tokens, and a loaded reviewer cost of $40 per hour.
- Copy generation: 1,500 input tokens and 400 output tokens per draft cost about $0.01. Three drafts plus an LLM-judge check come to about $0.04 per SKU.
- Image variants: four generated background or lifestyle images at an assumed $0.04 each add $0.16. Hero shots of the physical product stay with the photographer.
- Human-in-the-loop review: assume 70% of SKUs are low-risk at 90 seconds each ($1.00) and 30% are high-risk at 6 minutes each ($4.00). The blend is $1.90.
The total is about $2.10 per SKU. Assume the current baseline is $12 for a freelance description and $20 for lifestyle photography, or $32. Under these assumptions, review time is roughly 90% of the generative cost and tokens are a rounding error.
The cost of hallucination in product copy is set by how deep your review goes, so the choice between build and buy comes down to review tooling and PIM integration.
The options side by side:
| Option | Fits when | Breaks when |
|---|---|---|
| Platform features (Shopify Magic) | One storefront, simple attributes, no separate product information management (PIM) system | The PIM is the source of truth, you sell on several channels, or you need locale-specific brand rules |
| Buy PIM-native or vendor tooling | Attribute governance already lives in the PIM and you want drafts written back to it | The vendor can't show per-attribute review states or lets you pick only one model |
| Build | You need retrieval over spec sheets, custom risk tiers, or eval sets per category | Fewer than a few thousand SKUs, where engineering time outweighs the savings |
Questions to put to any vendor:
- Which attributes can the model write, and which are locked to PIM values?
- Is every generated field logged with prompt, model version, and reviewer?
- Can we export drafts and evals if we leave?
- How is copy quality measured at catalog scale: sampling, LLM judge, or human audit?
- Which provider processes our data, and is it retained for training?
B2B catalogs carry more risk: a wrong compatibility, tolerance, or certification value triggers returns and contract disputes. We recommend B2B teams start with PIM-native or custom builds that ground drafts in manufacturer spec sheets through retrieval-augmented generation, and keep the high-risk review tier wider than the model above assumes.
FAQ: Generative AI in retail and ecommerce
What is generative AI in retail and ecommerce?
How is generative AI being used in ecommerce?
How can I use generative AI in my ecommerce business?
How do you build generative AI in ecommerce?
How much does generative AI cost for an ecommerce store?
What are the risks of generative AI in ecommerce?
Start with one content pilot that ends in a decision
Run one content pilot on a single category, with product information management (PIM) attributes as the only source and a go or no-go threshold set before the first prompt.
An illustrative scope is 200-500 SKUs, structured output keyed to PIM fields, and human-in-the-loop review that logs the edit rate and every invented attribute. Compare reviewed output with your current copy on conversion and return rate, then decide whether to extend, retune, or stop.
Netguru's generative product description service follows this pilot format, and the Commerce Development team handles the PIM integration. To scope a pilot for your catalog, estimate your project.


