
Building a Data Annotation Platform

The client
Machine learning and big data have become central to how applications get built, from ecommerce through to healthcare. Data itself is now valuable enough that plenty of free services make their money collecting and selling it, often to train neural networks.
But data alone is rarely enough. Training a model usually needs human input — to teach a network to recognise a cat you must supply many pictures and mark the ones with a cat in them.
The challengeWhat the teams actually needed
That marking-up is called data annotation, and on a large dataset it is enormously time-consuming. It was the whole motivation for the platform.
Challenge 01Time
Annotating a large dataset by hand consumes an amount of time that makes prototyping impractical.
Challenge 02Prototyping speed
Machine learning applications need to be prototyped much more quickly than the annotation step allows.
Challenge 03Who does the work
The labour has to come from somewhere, and paying a team to do it internally does not scale.
What we did
Annotation delegated to the people who want the work
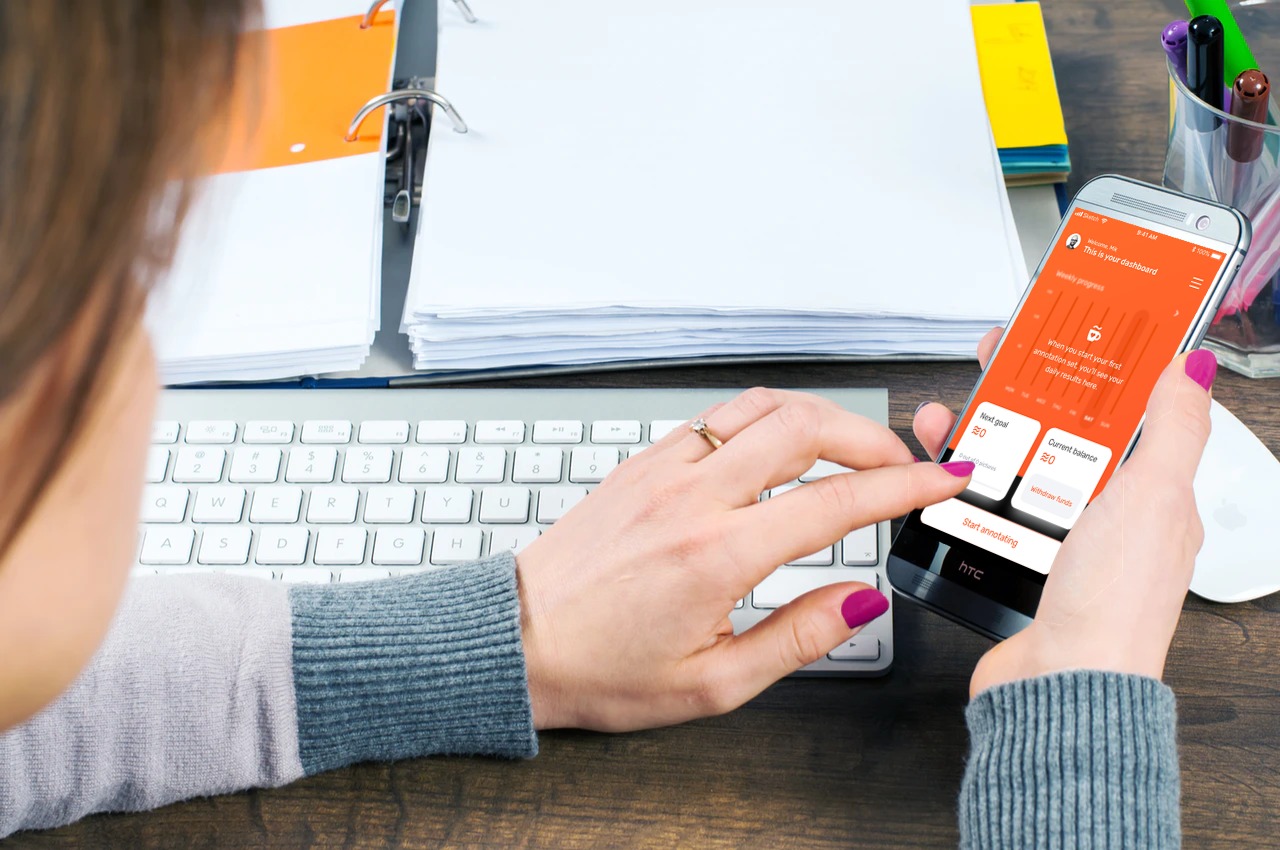
The Data Annotation Platform hands the labelling to users, who earn a little money for doing it — which is what makes prototyping a machine learning application considerably quicker.
Work passed outward
Annotating is delegated to users rather than absorbed by whoever is building the model.
Paid for the effort
Users earn a small amount for the annotation they complete, which is what keeps the supply of labelled data coming.
Prototypes sooner
Removing the annotation bottleneck lets a machine learning application be prototyped much faster than before.
Beyond one model
The approach generalises: any project needing labelled input at volume faces the same constraint.
Netguru quote
While the future of Libra remains unclear, it is already backed by several large financial companies. Understanding how Libra API works on our in house Data Annotation Platform, gave us a chance to get ahead of the game and prepare for the future applications of this cryptocurrency.
More like thisOther places we scaled product teams for growth.
What’s next